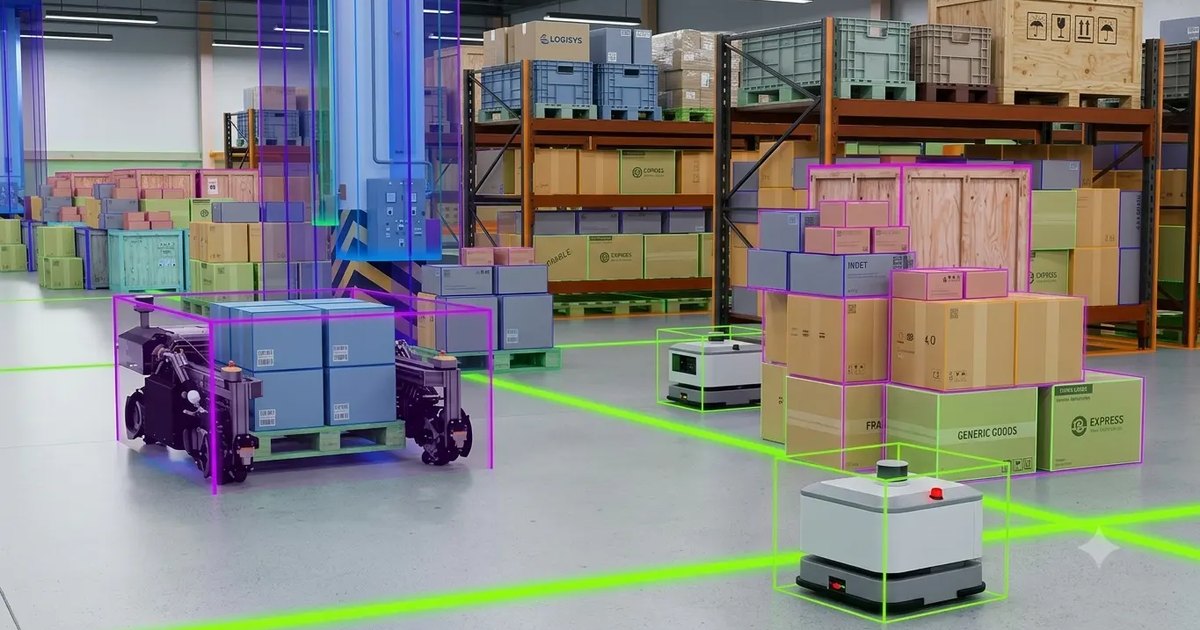
October 28, 2026
Synthetic Data for Computer Vision: What to Look For and Where to Get It
The six things to check in synthetic data for computer vision, from exact ground truth to realism, and how public datasets, in-house and platforms compare.
The six things to check in synthetic data for computer vision, from exact ground truth to realism, and how public datasets, in-house and platforms compare.
Key takeaways
Computer vision is the field of AI that teaches machines to understand images: spot objects, outline them, judge how far away they are. The models that do this are now widely available. What holds them back is the data they learn from.
A model learns by looking at images where the right answer is already marked. That answer is called the ground truth. Real photos are easy to collect, but marking the right answer on them is slow, costly and often inaccurate.
Synthetic data solves part of this problem. Only some kinds of synthetic data do, and not in every case. This guide explains what to look for, the evidence behind it, its limits and where to get it.
Physicl Studio, our tool for generating computer vision training data, is in private beta. Request access to try it on your own use case.
To learn, a vision model needs each image paired with the right answer. Depending on the task, that answer can be:
Getting these answers from real photos runs into three problems.
Some answers can't be drawn by hand. A person can draw a box or trace an outline. Nobody can type in the distance to every pixel, or the direction every surface faces. The team behind Apple's Hypersim put it plainly: "it is difficult or impossible to obtain per-pixel ground truth labels from real images". Depth sensors help, but they have blind spots. The authors of Depth Anything V2, an open depth model, found that real depth labels miss transparent objects and come out coarse at object edges and thin structures.
Rare cases stay rare. A model fails on what it has seen least: a cluttered shelf, a backlit doorway, a camera angle no one recorded. Collecting more photos mostly adds more of the common cases.
You can't change one thing at a time. To know whether lighting or clutter is what breaks your model, you need the same scene with only that one factor changed. Real photos almost never give you that. Each one differs from the next in a dozen ways at once.
The same limits apply to physical AI training more broadly. These are the gaps synthetic data is meant to fill.
Synthetic data for computer vision is images and video created by software instead of a camera, paired with the right answers for each frame. Teams use it to train and test models for tasks like detecting objects, outlining them and estimating depth.
The answers are what matter. A synthetic image on its own is just a picture. What turns it into training data is the ground truth that comes with it. For a wider look at how synthetic data is made, see our guide to synthetic data generation.
"Synthetic image" covers two very different things, and only one of them comes with reliable answers.
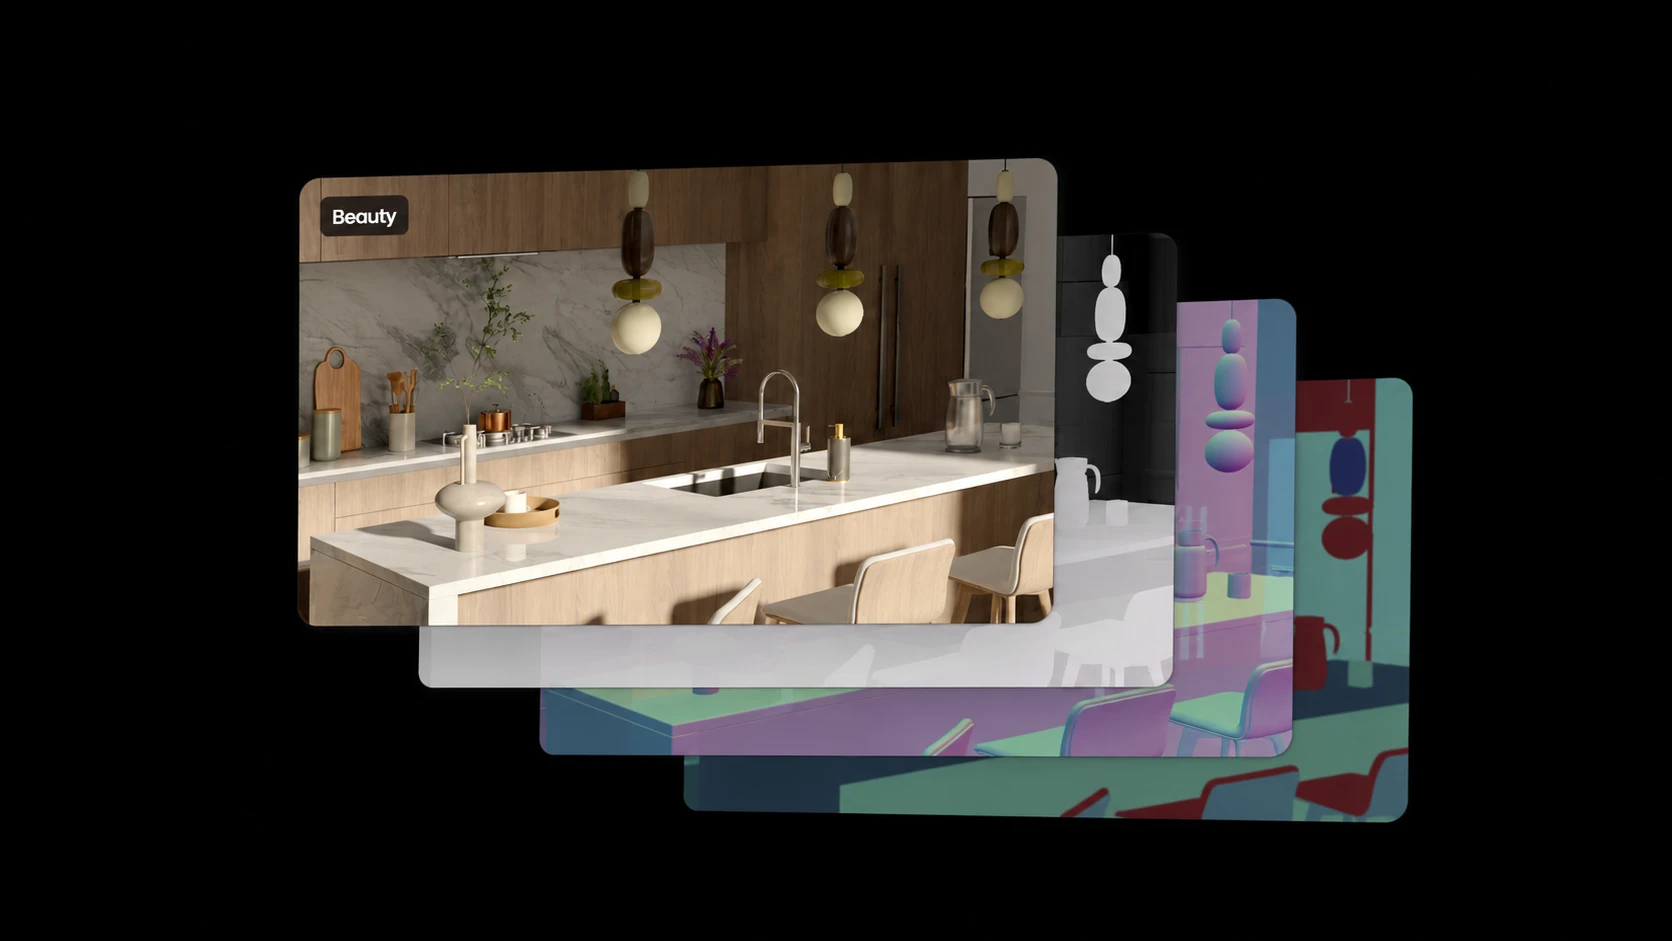
Rendered images are made from a 3D scene, the way an animated film is. The scene has a room, objects, lights and a camera. A renderer, the software that turns the scene into pictures, calculates how light travels through it to produce each frame. Because the software built the scene, it knows everything about it: the distance to each pixel, which object each pixel belongs to, which way each surface faces and where the camera stands. It saves all of this as separate layers next to each image. Nothing is guessed. The answers are read straight from the scene.
AI-generated images come from a generative model, such as a diffusion model, which has learned what images look like from millions of examples. They can look very real. But there is no scene behind them, only pixels. The model doesn't know how far away the table is or where one chair ends and the next begins. To train on these images, someone still has to label them, by hand or with another model, and that brings back the errors you were trying to avoid.
Both have a place. Generated images can add variety to a dataset that is already labeled. But if you need exact ground truth, images rendered from 3D scenes are the way to get it.
Not all synthetic data is worth training on. These six criteria separate data that improves a model from data that only adds volume. They apply to any source: a public dataset, a pipeline you build yourself or a commercial tool.
In short: every image should come with its answers, produced by the software that made it, not added afterwards.
For most vision tasks, that means several layers per frame: depth, surface normals, segmentation, camera pose (where the camera is and where it points) or any other metadata your task needs. Depth should ideally be metric depth, meaning real distances in meters, not just which object is closer.
This is the main reason research teams use synthetic data at all. The Depth Anything V2 team switched to synthetic images because, in them, fine details like edges, thin holes and small objects "are correctly labeled".
What to check: are the answers exact down to the pixel, and do they hold on glass, mirrors and thin parts?
In short: you should be able to change one thing in a scene and keep everything else the same.
Same room, same camera path, only the lighting changes. Or only the clutter. Two images that differ in a single factor are called counterfactual pairs. They let you run a controlled experiment, which researchers call an ablation, and see which factor your model depends on.
Changing many things at random also has value. NVIDIA's work on domain randomization showed it helps a model cope with new conditions. But random changes can't tell you why a model fails. Controlled changes can.
What to check: can you hold everything still except one factor, and is there a record of what changed?
In short: you should be able to make as much data as your training needs, quickly.
With real photos, more data means another round of collecting and labeling. Once a 3D scene exists, rendering another thousand frames is just computing time. Scale matters in practice: the Depth Anything V2 team trained the first stage of their model on 595,000 synthetic images.
What to check: how long does it take to go from a new request to new frames?
In short: the data should include the rare situations your real data misses.
Edge cases are the unusual conditions where models fail: low light, heavy clutter, odd camera angles, rare objects, shiny or see-through surfaces. With a 3D scene, a rare case is something you set up on purpose, not something you wait to capture. Synthetic data even covers cases sensors can't: the Depth Anything V2 team got the true depth of glass and reflective surfaces, which real depth sensors miss.
Fixed public datasets struggle here. Even good indoor scene datasets cover the rooms their authors chose, not the ones your model will face.
What to check: can you describe the scene your model gets wrong and get data for it?
In short: synthetic images should look like what a real camera sees.
A model trained on images that look artificial can struggle with real photos. This difference between synthetic and real images is called the sim-to-real gap, and it is the main risk of synthetic data. Path tracing, a rendering method that follows how light really bounces, gives realistic shadows, reflections and lighting, which keeps that gap small.
Realism alone isn't enough, but poor realism makes everything else harder.
What to check: are frames path-traced, and do materials and lighting behave like the real world?
In short: the data should work with your existing tools without extra code.
Training code expects data in common formats. For labels, one of the most common is COCO, named after a popular public dataset. For depth, teams use image formats that store exact numbers per pixel, such as EXR. If you have to write a converter before you can train, the data is costing you time.
What to check: can your training code read the output as it is?
Three studies show what synthetic data can do.
NVIDIA, 2018. Car detectors trained only on randomized synthetic images beat realistic synthetic data in two of three tests, and after a short extra round of training on real photos, beat models trained on real photos alone. Read the study.
Apple, 2021. Hypersim produced 77,400 photorealistic indoor images with per-pixel depth, surface normals and segmentation, for about $57,000. Read the study.
Depth Anything V2, 2024. Replacing real labeled photos with 595,000 synthetic images, together with a larger model and automatically labeled real photos, gave much finer and more robust depth predictions. Read the study.
In all three, synthetic data proved most valuable where exact labels matter, and worked best alongside real photos.
Synthetic data has real limits, and good teams plan for them.
Synthetic and real images are never identical. The Depth Anything V2 authors say it directly: "There exists distribution shift between synthetic and real images." A model trained only on renders can pick up the renderer's habits, such as perfectly clean edges, no camera noise and no motion blur. Other sensors face the same issue, as we covered in LiDAR simulation.
Synthetic data only covers the scenes someone built. The same paper notes that "synthetic images have restricted scene coverage." If your library holds a hundred kitchens and your model will work in warehouses, more kitchens won't help.
Building scenes takes work. Each scene needs 3D objects, materials and layouts that make sense. Poor scenes lead to poor data.
The answer is to combine synthetic and real data. NVIDIA fine-tuned on real photos after training on synthetic ones. The Depth Anything V2 team first trained a model on synthetic data, used it to label a large set of real photos, then trained their final model on those. Synthetic data brings exact answers, real photos bring real-world variety, and the best results use both. Whatever you train on, always test on real photos.
Synthetic data is most useful where answers are hard to get or rare cases matter.
The same data serves teams beyond classic computer vision. Robot perception needs the same depth and segmentation, seen from a robot's camera height. World models, AI models that predict how a scene will change, need geometry that stays consistent from frame to frame. They also face their own data sourcing problems.
There are three main sources, each with its own trade-off.
Public synthetic datasets. Hypersim, Virtual KITTI 2 and similar sets are free and come with exact answers, but their scenes are fixed. You can't add the room your model gets wrong or change one factor. Check the license before commercial use.
A pipeline you build yourself. Tools like Blender or Unreal Engine give full control, but you need 3D artists and engineers, and it takes a while to get the first useful frame.
A synthetic data platform. Scenes, rendering and ground truth in one place. You set what changes, and it renders the frames with their answers. Judge it on the six criteria above.
Physicl is the synthetic data platform for physical AI, and Studio is how teams generate computer vision training data on it. It was built around the six criteria above.
You describe the scene your model is missing, or start from a library of more than 10,000 scenes and 100,000 objects. You choose what changes between runs, such as lighting, layout, clutter or camera path. Everything else holds still. Studio then renders images and video with ground truth on every frame.
Studio is in private beta, open to a small group of ML researchers and engineers. Request access to try it on your own use case, or talk to us about what your models need.